Jev has been everywhere since launch—but a lot of people are still asking the same question: what exactly does it do?
Here's the simplest explanation:
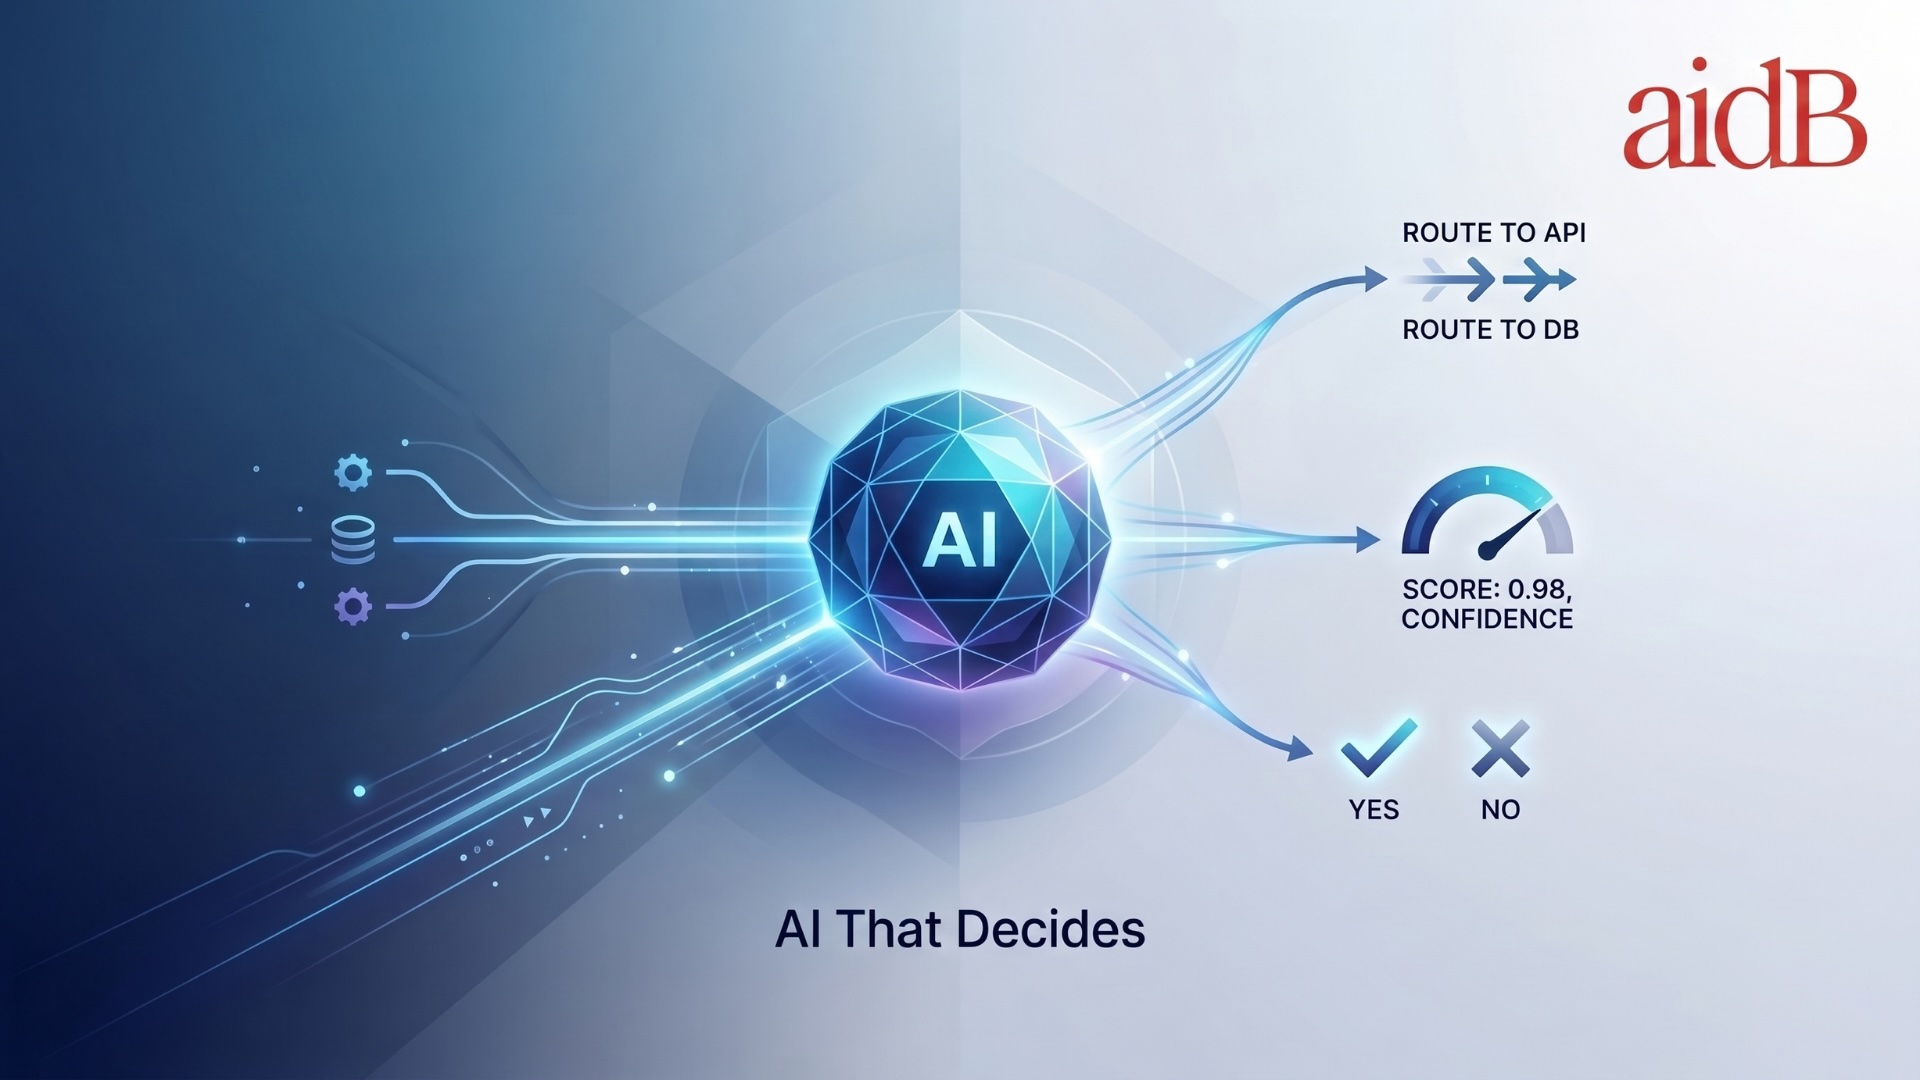
ChatGPT generates answers. Jev makes decisions.
TypeSafe AI launched Jev on September 15 as the first model in a new category it calls System One Models. Instead of generating paragraphs, code, or conversations, Jev takes information and returns structured decisions that software can immediately use.
Think:
Which department should handle this ticket?
Is this transaction suspicious?
Which AI model should handle this request?
How urgent is this email?
Should this AI agent continue, retry, or stop?
That distinction explains almost everything about Jev.
Jev is a probabilistic decision model for software.
You give it:
1. Some information — the “state”
2. A question about that information
3. The possible answers
Jev returns the answer plus probabilities/confidence information.
It does not write an explanation afterward.
Imagine receiving this customer message:
“My payouts have been failing for three days and I need this fixed immediately.”
A normal LLM might respond:
“This appears to be an urgent technical issue related to payments…”
Jev might instead return something conceptually like:
Department: Billing — 87%
Urgent: Yes — 95%
Frustration: Frustrated — 96%
Your software can immediately act on those values.
That's Jev.
This is probably the biggest source of confusion.
LLMs can already return structured JSON.
But they still fundamentally generate text tokens sequentially, then your application validates and parses the result.
TypeSafe built Jev specifically around the opposite idea:
Don't generate the explanation if the software only needs the decision.
Jev evaluates predefined questions and returns typed outputs directly. Multiple questions can also be evaluated in parallel.
So instead of paying an LLM to effectively say:
“After considering the customer message, I believe the appropriate department is billing…”
you get:
billing
plus probabilities.
Because removing text generation changes the economics considerably.
TypeSafe currently reports Jev at approximately:
70–500 ms end-to-end latency
and:
$0.042 per million input tokens
with output currently priced too cheaply for the company to meter separately.
TypeSafe's own workflow evaluations report performance reaching 193.6× faster and 444.6× cheaper than the LLM workflows it compared against.
Important caveat:
Those are TypeSafe's own evaluations, and the company itself notes that the numbers are likely toward the high end of real-world gains and that some evaluator-design bias could exist.
The broader point is simpler:
If your application makes millions of tiny AI decisions, generating paragraphs for every decision is expensive and slow.
Jev is designed for that layer.
This is the easiest way to understand how Jev works.
It currently revolves around three decision types.
Ask Jev to select from predefined possibilities.
Example:
Which department should handle this ticket?
Possible answers:
Billing
Technical
Sales
Jev returns a selection plus probabilities for the alternatives.
Think of this as a probabilistic yes/no question.
Example:
Is this customer message urgent?
Instead of merely returning true, Jev might return something like:
0.95
Meaning the model assigns high probability to “yes.”
Ask Jev to evaluate something across an ordered scale.
Example:
How frustrated is this customer?
Your scale could be:
Calm → Frustrated → Very Angry
Jev returns a score plus its probability distribution/confidence.
Let's build the simplest useful example:
Incoming customer messages will automatically be evaluated for:
Department
Urgency
Frustration
Start at TypeSafe AI and access Jev through its developer interface/API.
Jev is also already available through platforms including Vercel AI Gateway and Cloudflare Workers AI, making it easier to plug into existing developer stacks.
This is an important point:
Jev isn't primarily an app you sit down and chat with.
It's infrastructure that developers put inside other products.
The state is simply the information Jev should evaluate.
For our example:
Help! My payouts have been failing for three days and I need this fixed immediately.
The state could also be:
Jev currently supports up to a 32,000-token context window in Cloudflare's implementation.
Now tell Jev exactly what decisions you need.
Conceptually:
department:
Billing
Technical
Sales

is_urgent:
Yes / No

frustration:
Calm
Frustrated
Very Angry
Notice what we're not doing.
We're not asking:
“Analyze this ticket and explain what we should do.”
We define the answers our software understands before the model runs.
A request could conceptually look like:
STATE:
"My payouts have been failing for three days."

QUESTIONS:

Department:
- Billing
- Technical
- Sales

Urgent:
- Yes
- No

Frustration:
- Calm
- Frustrated
- Very Angry
Jev evaluates these questions against the same state in parallel rather than writing separate responses for each one.
That's part of why the model is interesting for large-scale automation.
Suppose Jev gives you:
Department: Billing — 87%
Urgent: 95%
Frustration: Frustrated — 96%
Don't just use the winning answer.
The probabilities are arguably the more interesting part.
You can create rules like:
If confidence > 90%:
→ Route automatically

If confidence = 70–90%:
→ Route, but flag for review

If confidence < 70%:
→ Send to a human
Now uncertainty becomes part of your application logic.
This is the part that makes Jev click.
Jev doesn't need to do everything.
Your ordinary software handles the action.
For example:
IF department = billing
AND urgency > 0.90

THEN:
→ Send ticket to Priority Billing queue
Jev supplies the judgment.
Your code controls what happens next.
TypeSafe describes this approach as building “smart if-statements” into software.
This may ultimately be the bigger use case.
Imagine an AI agent has five possible tools:
Search web
Read database
Send email
Generate code
Ask the user
Normally, a general LLM might decide which tool to use.
But if an agent is making thousands of these tiny routing decisions, those model calls can become expensive and slow.
Jev can sit in the loop and answer:
Which tool should execute next?
Or:
Should we continue, retry, ask the user, or stop?
Vercel specifically highlights these kinds of agent-routing decisions as Jev use cases.
So an architecture might become:
User request
↓
LLM understands the task
↓
Jev makes repeated routing decisions
↓
Tools execute
↓
LLM generates the final human-facing answer
Jev doesn't necessarily replace the LLM.
It handles a different part of the system.
Only days after Jev's launch, LangChain published its own experiments integrating Jev into agent architecture.
Its examples include:
LangChain describes the core opportunity clearly: agent loops often require many model calls just to make decisions, making those loops slower and more expensive.
On September 21, LangChain also added Jev as a judge inside LangSmith Evals.
That's a strong signal for where this technology might fit:
AI evaluating AI.
Imagine your support agent produces this answer:
“Your refund has been approved and should arrive tomorrow.”
Before sending it, Jev could evaluate:
Did the agent promise something unsupported?
Does the response contain sensitive information?
Does it comply with refund policy?
Should a human review this response?
Then your application decides whether the message is sent.
That creates a layer:
Agent → Jev evaluates → Software decides → User receives
LangChain's early testing found Jev particularly interesting for agent evaluation, although it explicitly describes those results as promising but still early.
TypeSafe sometimes describes Jev as having zero hallucinations because its output types are constrained.
There's an important distinction here.
If the only valid options are:
Billing
Sales
Technical
Jev cannot suddenly answer:
“Marketing Department.”
That's what the type constraint prevents.
But Jev can still choose the wrong valid answer.
For example:
Billing — 92%
could still be incorrect.
So:
Type-safe ≠ always correct.
The valuable part is that the output format is controlled and uncertainty is exposed so your application can choose when to automate and when to escalate. TypeSafe itself emphasizes confidence thresholds and human review for uncertain decisions.
Don't use Jev to:
Write your newsletter
Draft an email
Generate code explanations
Brainstorm business ideas
Have conversations
Write a marketing campaign
That's what general LLMs are for.
Use Jev when the question looks more like:
Given this information, which predefined action should my software take?
That's the mental model.
Here's where this can become commercially useful.
Imagine a roofing company receives 5,000 inquiries each month.
Jev could evaluate each inquiry for:
Service type
Location eligibility
Lead quality
Urgency
Commercial vs. residential
Likely spam
Then your workflow can automatically:
High-value lead → Sales immediately
Emergency repair → Priority queue
Wrong geography → Automated response
Low confidence → Human review
Spam → Filter
The intelligence becomes an invisible layer behind the business.
The business opportunity isn't:
“I'll sell Jev prompts.”
Jev points toward something broader:
Companies have enormous numbers of repetitive judgment calls:
Today, many of those decisions are either:
Hard-coded rules
or:
Expensive LLM calls.
Jev is trying to occupy the space between them.
A developer or automation consultant could offer:
“I'll identify the high-volume decisions inside your business and automate the ones AI can safely classify.”
That's potentially much more valuable than another chatbot implementation.
When deciding whether Jev fits a task, ask one question:
Can I define the possible answers before the AI sees the input?
If no:
Use an LLM.
If yes:
Jev may be worth testing.
Examples:
“Write a response to this customer.”
→ LLM
“Which department should receive this customer?”
→ Jev
“Explain this legal document.”
→ LLM
“Does this document satisfy one of these predefined conditions?”
→ Potential Jev task
That's the simplest mental model I've found.
A practical walkthrough of Jev covering model routing, Choice/Score/Noul, costs, speed, and real-world demos.
Video: Watch on YouTube
Why watch: Probably the fastest way to make Jev's unusual “decisions, not text” concept click.